
Databricks Certified Machine Learning Professional - Databricks-Machine-Learning-Professional Exam Practice Test
A Machine Learning Engineer is considering moving their functions and unit tests from notebooks into separate Python files (e.g., modules and test scripts) to take advantage of the numerous benefits of this approach like automated execution, code reusability, and version control. Which challenge should the engineer consider with this approach?
Correct Answer: C
Explanation: Only visible for TrainingDump members. You can sign-up / login (it's free).
A Machine Learning Engineer needs to develop fraud detection models with Databricks. They need to ensure seamless collaboration between data engineers and data scientists while maintaining strict governance, version control, and traceability as models progress from development to production. So, they need to choose the Databricks feature that will enable centralized model lineage tracking, cross-workspace access control, and automated synchronization of model versions with their training data. Which Databricks feature will do this?
Correct Answer: D
Explanation: Only visible for TrainingDump members. You can sign-up / login (it's free).
A machine learning engineering manager has asked all of the engineers on their team to add text descriptions to each of the model projects in the MLflow Model Registry. They are starting with the model project "model" and they'd like to add the text in the model_description variable.
The team is using the following line of code:
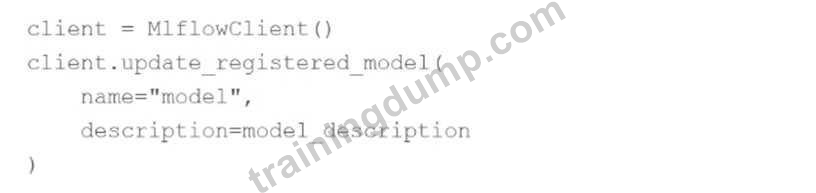
Which change does the team need to make to the above code block to accomplish the task?
The team is using the following line of code:
Which change does the team need to make to the above code block to accomplish the task?
Correct Answer: D
A Machine Learning Engineer is building a Databricks ML pipeline to predict customer churn. The pipeline needs to include automated feature engineering, model training, evaluation, and deployment to a REST API endpoint using MLflow. What is the primary goal of an integration test for this pipeline?
Correct Answer: C
Explanation: Only visible for TrainingDump members. You can sign-up / login (it's free).
A machine learning engineer is developing a recommendation system for online content. They are using the Databricks Feature Store to store features for training and inference. Which unit test should they create?
Correct Answer: A
Explanation: Only visible for TrainingDump members. You can sign-up / login (it's free).
A machine learning engineer wants to log and deploy a model as an MLflow pyfunc model. They have custom preprocessing that needs to be completed on feature variables prior to fitting the model or computing predictions using that model. They decide to wrap this preprocessing in a custom model class ModelWithPreprocess, where the preprocessing is performed when calling fit and when calling predict. They then log the fitted model of the ModelWithPreprocess class as a pyfunc model. Which statement is a benefit of this approach when loading the logged pyfunc model for downstream deployment?
Correct Answer: E
A machine learning engineer wants to delete an active MLflow Model Registry Webhook with webhook ID webhook_id for a specific model.
They are using the following code block:
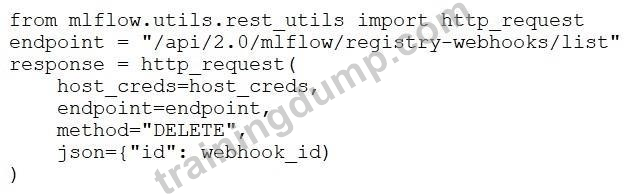
Which change does the machine learning engineer need to make to this code block so it will successfully accomplish the task?
They are using the following code block:
Which change does the machine learning engineer need to make to this code block so it will successfully accomplish the task?
Correct Answer: C
Explanation: Only visible for TrainingDump members. You can sign-up / login (it's free).
A data scientist wants to examine the data in the Feature Store table table from the database dev as a Spark DataFrame. They have access to Feature Store Client fs. Which line of code can be used to gel the data from table as a Spark DataFrame?
Correct Answer: B
Explanation: Only visible for TrainingDump members. You can sign-up / login (it's free).
Which of the following is an obstacle related to streaming machine learning applications?
Correct Answer: D
Explanation: Only visible for TrainingDump members. You can sign-up / login (it's free).
A Machine Learning Engineer uses Lakehouse Monitoring to track their credit scoring model's performance. The existing profile metrics table contains three aggregate metrics:
- adefault_risk_score
- payment_history_score
- credit_utilization_score
They need to:
1. Create a composite risk rating that combines these three scores using weights of 0.5, 0.3, and 0.2 respectively.
2. Monitor drift of this composite score against an established baseline.
Which approach should be used to implement both requirements within Lakehouse Monitoring?
- adefault_risk_score
- payment_history_score
- credit_utilization_score
They need to:
1. Create a composite risk rating that combines these three scores using weights of 0.5, 0.3, and 0.2 respectively.
2. Monitor drift of this composite score against an established baseline.
Which approach should be used to implement both requirements within Lakehouse Monitoring?
Correct Answer: B
Explanation: Only visible for TrainingDump members. You can sign-up / login (it's free).
A Machine Learning Engineer needs to develop a custom anomaly detection model that monitors the internal IT infrastructure of their company. The model takes in compute metrics, logs, and user data and generates a binary prediction. The engineer plans to deploy it as a Databricks Model Serving endpoint. In production there will only be one client calling the endpoint once every
15 seconds. Leadership sees the model as an important part of their operational improvement strategy so maintaining consistent, stable, low latency inference is a requirement while minimizing infrastructure costs. The engineer plans to deploy the endpoint via the MLflow Deployment SDK.
Which endpoint config for the MLflow Deployment SDK should the engineer select?
15 seconds. Leadership sees the model as an important part of their operational improvement strategy so maintaining consistent, stable, low latency inference is a requirement while minimizing infrastructure costs. The engineer plans to deploy the endpoint via the MLflow Deployment SDK.
Which endpoint config for the MLflow Deployment SDK should the engineer select?
Correct Answer: A
Explanation: Only visible for TrainingDump members. You can sign-up / login (it's free).
A machine learning engineer wants to programmatically create a new Databricks Job whose schedule depends on the result of some automated tests in a machine learning pipeline. Which Databricks tool can be used to programmatically create the Job?
Correct Answer: A
A Data Scientist at a company with rapidly increasing sales has deployed a scikit-learn model in production, which is retrained weekly on a single-node cluster. During the most recent retraining, the job failed due to an out-of-memory error. Upon investigation, the Data Scientist discovered that the training data had increased to 700GB as a result of the company's expanding customer base. Which approach will reliably resolve this issue in the long term?
Correct Answer: A
Explanation: Only visible for TrainingDump members. You can sign-up / login (it's free).
A Data Scientist needs to perform inference on a continuously updated Delta table called sales_data using an MLflow-registered Spark ML pipeline model (catalog.prod.sales_forecaster).
Predictions must be written to a Delta table forecast_results, which must be updated with low latency leveraging a cluster with three executors. They want to maximize the efficient use of their cluster when doing this. Which approach will suit their needs?
Predictions must be written to a Delta table forecast_results, which must be updated with low latency leveraging a cluster with three executors. They want to maximize the efficient use of their cluster when doing this. Which approach will suit their needs?
Correct Answer: A
Explanation: Only visible for TrainingDump members. You can sign-up / login (it's free).
A Data Scientist is preparing a Spark ML pipeline on a customer dataset with numeric features age, annual_income, and transaction_count, each varying widely. Because the chosen algorithm requires inputs normalized to the [0,1] range, they need to apply the appropriate Spark ML transformer to these features. Which Spark ML transformer should the Data Scientist use to scale all features to the [0,1] range?
Correct Answer: D
Explanation: Only visible for TrainingDump members. You can sign-up / login (it's free).